CREATE a Vector Index
- reference
Use a CREATE statement to create a vector index for approximate nearest neighbor (ANN) search on a remote or standalone collection.
An Operational Insights vector index, of type VTREE, stores the embeddings from a single vector field and organizes them into a routing tree of leaf clusters.
The query optimizer uses a VTREE index to accelerate approximate nearest neighbor (ANN) queries, pruning the search to a subset of clusters instead of scanning every record.
For more information about the query-side functions that use this index, see Vector Functions.
An Operational Insights vector index covers only 1 vector field.
Before you create a vector index on a collection, you must run ANALYZE COLLECTION on that collection to gather the samples the index build requires.
Creating a vector index on a collection with no samples fails.
For more information, see Collecting Samples.
|
Syntax
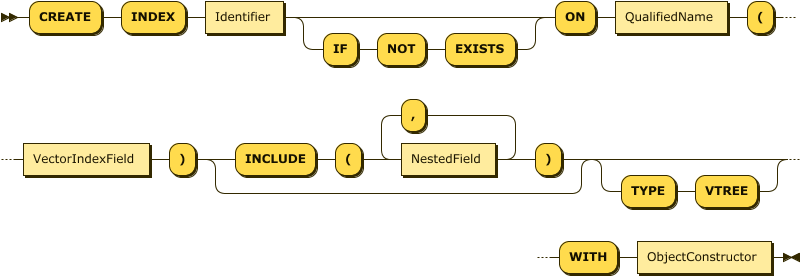
CreateVectorIndex EBNF
CreateVectorIndex ::= "CREATE" "INDEX" Identifier ("IF" "NOT" "EXISTS")?
                       "ON" QualifiedName
                       "(" VectorIndexField ")"
                       ("INCLUDE" "(" NestedField ( "," NestedField )* ")")?
                       ("TYPE" "VTREE")?
                       "WITH" ObjectConstructor
CreateVectorIndex Diagram
Show VectorIndexField Diagram
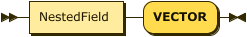
Show NestedField Diagram
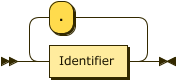
Examples
The following example creates a vector index on the review_vector_emb field, specifying only the mandatory dimension and similarity parameters and omitting the optional TYPE clause:
 CREATE INDEX review_vector_idx
 ON products.ptype.product (review_vector_emb VECTOR)
 WITH {"dimension": 384, "similarity": "cosine"};
Show additional examples
The following example creates a vector index and uses the INCLUDE clause to replicate the rating and genre fields in the index.
A query that filters on rating or genre and orders by vector distance can then be served entirely from the index, without a lookup against the base collection.
 CREATE INDEX review_vector_idx
 ON products.ptype.product (review_vector_emb VECTOR)
 INCLUDE (rating, genre)
 TYPE VTREE
 WITH {"dimension": 384, "similarity": "cosine"};
The following example fine-tunes the index build and storage behavior by overriding the default settings for train_list_fraction, quantization, epsilon, and num_clusters:
 CREATE INDEX ix_vtree
 ON Entertainment.Movie (embedding VECTOR)
 INCLUDE (title, vote_average, revenue)
 TYPE VTREE
 WITH {
     "dimension": 384,
     "similarity": "cosine",
     "train_list_fraction": 0.2,
     "quantization": "SQ8",
     "epsilon": 0.25,
     "num_clusters": 1000
 };
You can drop a vector index the same way you drop any other index. For more information, see DROP Statements.
DROP INDEX Entertainment.Movie.ix_vtree IF EXISTS;Arguments
- Identifier
-
For the
CREATE INDEXstatement, the firstIdentifieris the index name.
- QualifiedName
-
The
QualifiedNameidentifies the collection to build the index on.
- VectorIndexField
-
The
VectorIndexFieldconsists of aNestedFieldthat specifies the vector field to index, followed by theVECTORkeyword. The field must contain an array of floating point numbers with the dimensionality specified in theWITHclause. You can have only 1 vector field per vector index.
- INCLUDE
-
The optional
INCLUDEclause replicates the listed non-key fields directly in the vector index. When you omitINCLUDE, the index stores only the primary key and the vector field. Replicating fields in the index lets the query optimizer take ANN query paths that filter on those fields from within the closest leaf clusters, instead of looking up each candidate record in the base collection.Unlike a standard index, do not specify a type for an
INCLUDEfield in a vector index. Specifying a type for anINCLUDEfield causes a compilation error.
- TYPE
-
The optional
TYPEclause specifies the index type.VTREEis the only supported vector index type, and it’s the default when you omitTYPE.
- WITH
-
The
WITHclause is mandatory for a vector index. ItsObjectConstructorrepresents an object containing key-value pairs, one for each parameter. You can define the following parameters:Name Description Schema dimension
RequiredThe dimensionality of the vector field. This specifies the length of the vector arrays stored in the indexed field, such as 384 for a common sentence-transformer model.
integer
similarity
RequiredThe distance or similarity metric used to train and query the index. Accepts one of the following string values:
-
euclidean -
l2 -
euclidean_squared -
l2_squared -
cosine -
dot(supported only for normalized embeddings in this release)
enum: euclidean, l2, euclidean_squared, l2_squared, cosine, dot
train_list_fraction
OptionalThe decimal fraction of dataset records, ranging from 0.0 to 1.0, sampled to train the leaf centroid structure during index creation, such as
0.1for 10% of the dataset.
Default:0.1float
quantization
OptionalThe scalar quantization applied to stored vectors to reduce index size and speed up distance computation, at the cost of a small reduction in recall. Accepts
SQ4(4-bit) orSQ8(8-bit).
Default:SQ8enum: SQ4, SQ8
epsilon
OptionalA fractional tolerance, greater than 0, that extends the search radius beyond the closest cluster boundary during index insertion and ANN query execution. A larger epsilon increases recall at the cost of visiting more clusters.
Default:0.75float
num_clusters
OptionalThe number of leaf clusters created in each storage partition.
Default: the square root of the partition’s cardinality.integer
seed
OptionalA seed value for the index build’s random number generator. Set a specific value to reproduce the same exact index structure each time you create the index.
Default: a random value, unless you specify oneinteger
-
This parameter table, including the accepted similarity values and every default value, reflects the vector search design at the time of writing and is subject to change before general availability.
If a record’s vector field is missing, null, of the wrong type, or of the wrong dimensionality, Operational Insights excludes that record’s embedding from the index and shows a warning, instead of failing the index build.
|